Alibaba Qwen3.6-35B-A3B: Sparse MoE Model with 3B Active Params
Alibaba’s Qwen3.6-35B-A3B is a sparse MoE with 3B active params, strong coding and multimodal vision results, plus GGUF for local 4-bit runs.
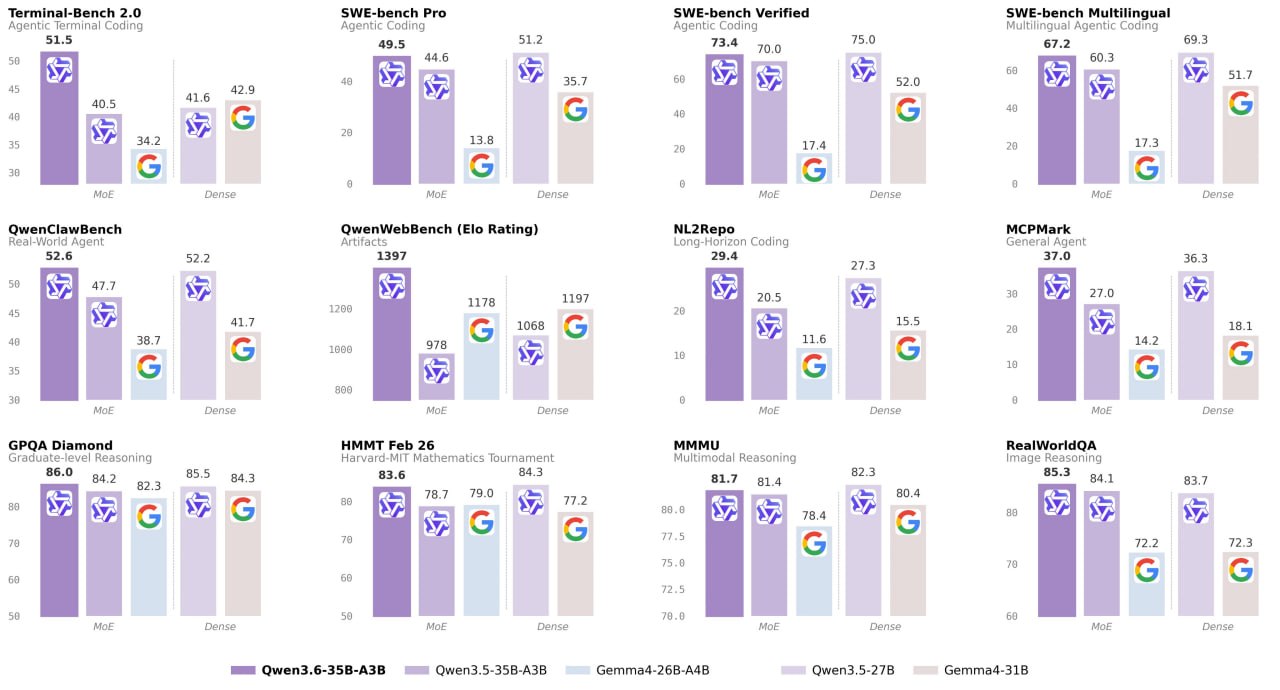
Alibaba released Qwen3.6-35B-A3B today.
This is a sparse MoE: 35 billion parameters, with only 3 billion active.
It outperforms the dense model Qwen3.5-27B (27 billion parameters) on a number of key coding benchmarks and significantly surpasses its direct predecessor Qwen3.5-35B-A3B, especially in agentic coding and reasoning tasks.
Qwen3.6 is multimodal from the start, and Qwen3.6-35B-A3B demonstrates perception and multimodal reasoning capabilities that far exceed expectations for its size, with only ~3 billion active parameters.
On most vision-language benchmarks, its results are comparable to Claude Sonnet 4.5 and even surpass it on a number of tasks. Particularly notable are its strengths in spatial intelligence: 92.0 on RefCOCO and 50.8 on ODInW13.
Unsloth GGUF, so the model can be run locally on 23 GB RAM / Mac in 4-bit mode. (guide)
Comments
Weekly digest
The best of vibe coding, AI agents and open source — once a week, no spam.
Related articles
All articlesQwen3.6 35B A3B vs Gemma4 26B A4B: MoE Vibe-Coding Face-Off
Two MoE models take the same vibe-coding challenge: Qwen3.6 35B A3B vs Gemma4 26B A4B on Unsloth Q6_K_XL + llama.cpp across 4 prompts.
GLM-5.3 Flash Released: Zhipu's New AI Model Beats GLM-5.2
Zhipu officially releases GLM-5.3 Flash, scoring 84.3 on Terminal-Bench, outperforming GLM-5.2 at 10x lower cost. Open weights, MIT license, 1M context.
Graph-Based Multimodal RAG for Document Processing on LightRAG
Open-source, graph-based universal multimodal RAG system built on LightRAG to process documents and unify text, images, tables, and more.