Gemopus-4-26B-A4B-it GGUF: Opus-Tuned Gemma 4 for Local Inference
Quantized Gemma 4 trained on Opus data with instruction tuning. Runs in LM Studio, Ollama, GPT4All, or llama.cpp; needs ~16–24GB RAM/VRAM.
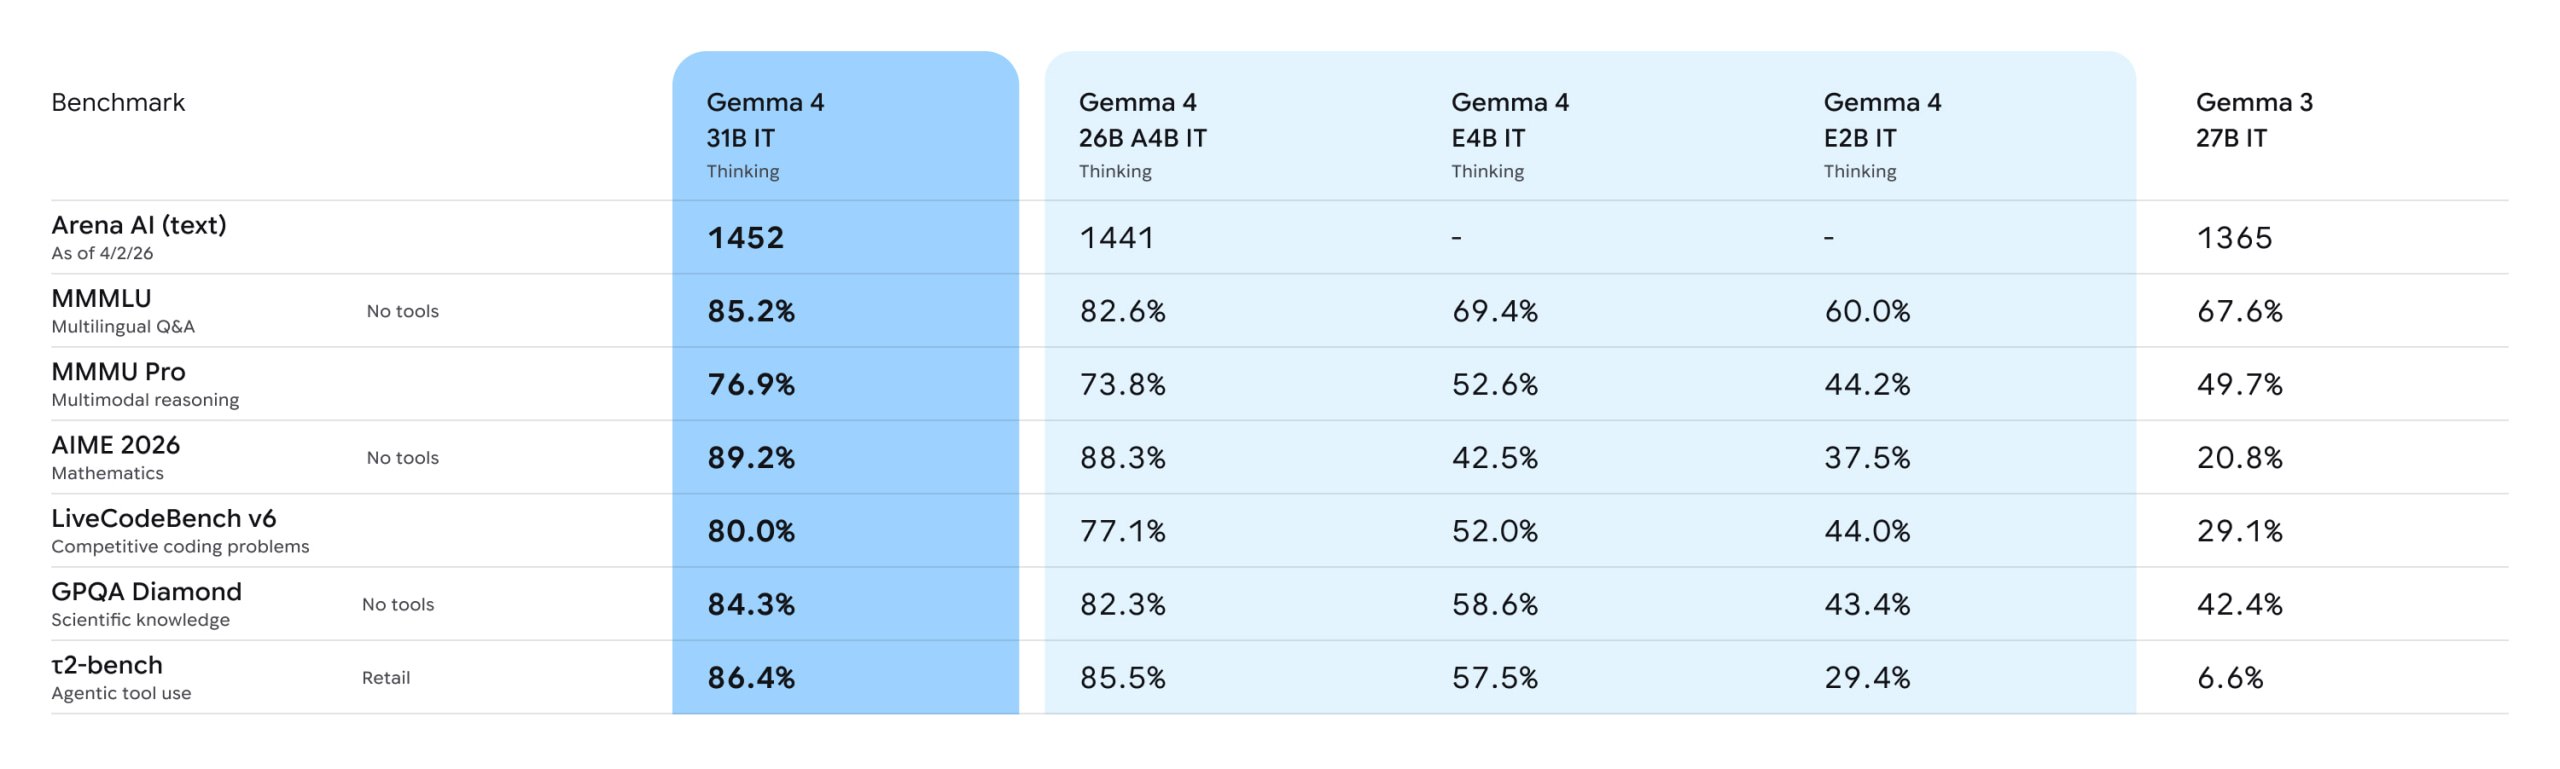
Gemopus-4-26B-A4B-it GGUF
On Hugging Face, an enthusiast posted a quantized Gemma 4 trained on Opus data.
I think anyone who has used Opus knows that its advantage is the quality of its answers: compared to most LLMs, they’re probably the most natural and most readable.
Instruction-tuned (it) means it was specifically fine-tuned for precise commands and dialogues.
It will run in LM Studio, Ollama, GPT4All, or via bare llama.cpp.
For comfortable use with Q4_K_M or Q5 quantization, you’ll need about 16–24 GB of RAM/VRAM in total.
Comments
Weekly digest
The best of vibe coding, AI agents and open source — once a week, no spam.
Related articles
All articlesDigUp: EmbeddingGemma 2 Powered Local Search App for macOS
DigUp uses Google’s open‑source EmbeddingGemma 2 to deliver fast, on‑device search of files, PDFs, photos, podcasts and videos on macOS.
OpenAI expands GPT‑6.1 context window to 500k tokens by default
OpenAI raised the default context window of GPT‑6.1 in Codex and ChatGPT Work from 272k to 500k tokens, with plans for further expansion.
Animator: AI-Powered Hand‑Drawn Video Generator from Text Prompts
Animator creates narrated hand‑drawn animation videos from a simple text prompt in seconds, generating script, scenes, narration and icons via Python.