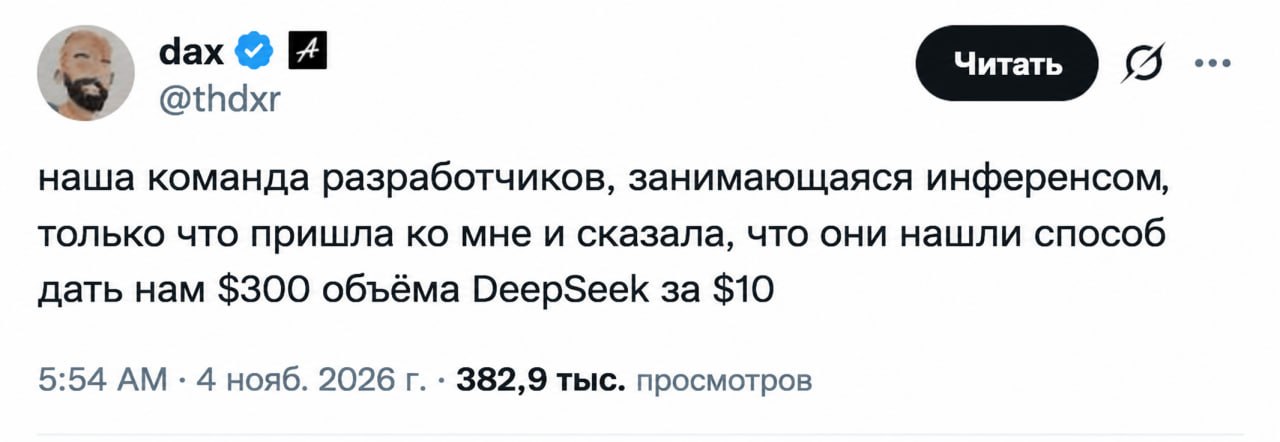
OpenCode Boosts DeepSeek Efficiency 30× – $10 Gets $300 Power
OpenCode’s co‑founder reveals a method to make DeepSeek 30 times more cost‑effective – $10 now delivers the performance that used to cost $300.
 cpaua1 min24
Filter by tag
OpenCode’s co‑founder reveals a method to make DeepSeek 30 times more cost‑effective – $10 now delivers the performance that used to cost $300.
cpaua1 min24NVIDIA's DeepSeek‑V4.1‑Flash‑1017 model is 81 GB smaller with only a 0.7‑point drop in Terminal‑Bench and 0.26 in SciCode, keeping near‑original performance for production inference.
cpaua1 min72OpenCode adds Claude subscription, raises DeepSeek V4.1 limit to $100 on the $10 Go plan, and adds an image generation tool for OpenAI, Gemini, Grok, etc.
cpaua1 min202DeepSeek V4.1-Flash (763B) runs on consumer GPUs with 12 GB VRAM using GSQ‑RCO quantization, reaching up to 231 tokens/s input processing, but requires ~239 GB storage.
cpaua2 min260DeepSeek has released the source code of DeepInfer, its inference engine, on GitHub. The open‑source tool speeds up model serving, lowers costs and runs on Nvidia and Huawei hardware.
cpaua1 min142DeepSeek V4.1 Flash 1017 delivers 244 tokens per second, beating GPT‑6.1 Sol, priced at $500/month. Its web‑search API is free until Oct 31, then $0.75 per 1k requests.
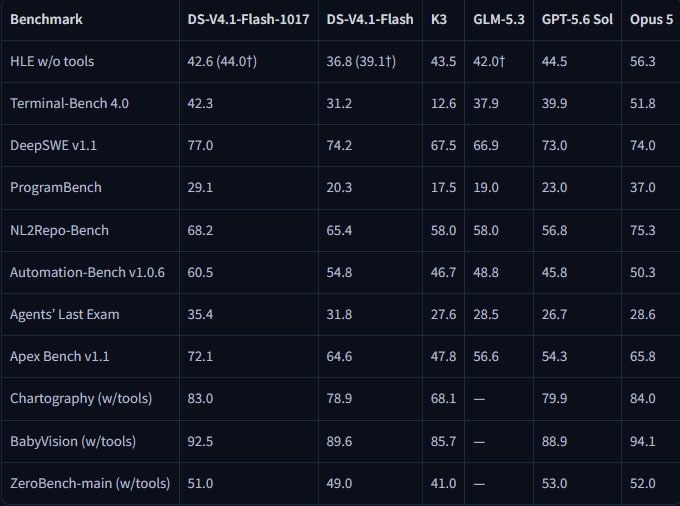
cpaua1 min354DeepSeek 4.1-1017 matches Opus 5, excels in 3D, coding, agents, visual tasks, offers a 1M‑token window, cheap pricing, and is available via app, web and API.
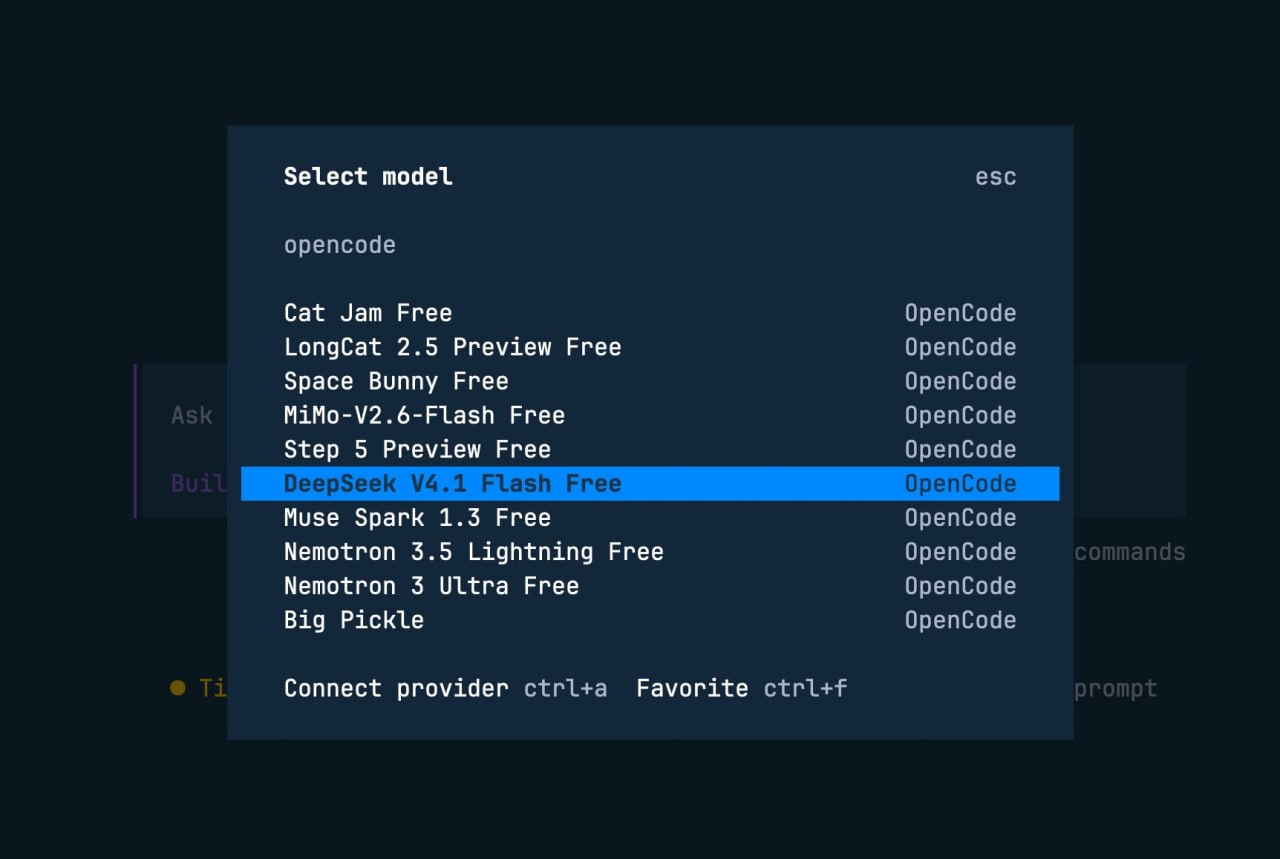
cpaua1 min200DeepSeek V4.1 Flash is now available for free on OpenCode, but the free tier caps the context window at 200,000 tokens.
cpaua1 min200DeepSeek launches Harness desktop client for Windows 64‑bit and Mac Apple Silicon, offering a simple double‑click install without Node or terminal.
cpaua1 min422DeepSeek adds four text‑to‑speech voices—Mira, Echo, Stella, Tide—and keeps V4 Pro active alongside V4.1 Flash with unchanged pricing after Sep 14.
cpaua1 min308