DeepSeek V4.1-Flash 763B Runs Locally on 12GB GPU with Quantization
DeepSeek V4.1-Flash (763B) runs on consumer GPUs with 12 GB VRAM using GSQ‑RCO quantization, reaching up to 231 tokens/s input processing, but requires ~239 GB storage.
Filter by tag
DeepSeek V4.1-Flash (763B) runs on consumer GPUs with 12 GB VRAM using GSQ‑RCO quantization, reaching up to 231 tokens/s input processing, but requires ~239 GB storage.
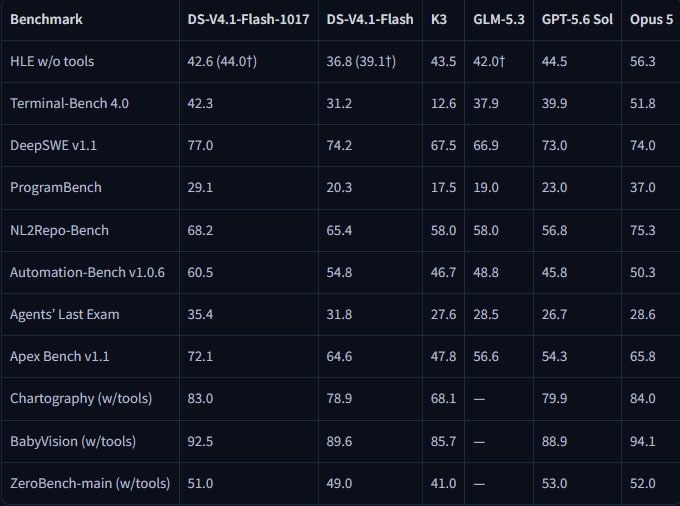
DeepSeek 4.1-1017 matches Opus 5, excels in 3D, coding, agents, visual tasks, offers a 1M‑token window, cheap pricing, and is available via app, web and API.
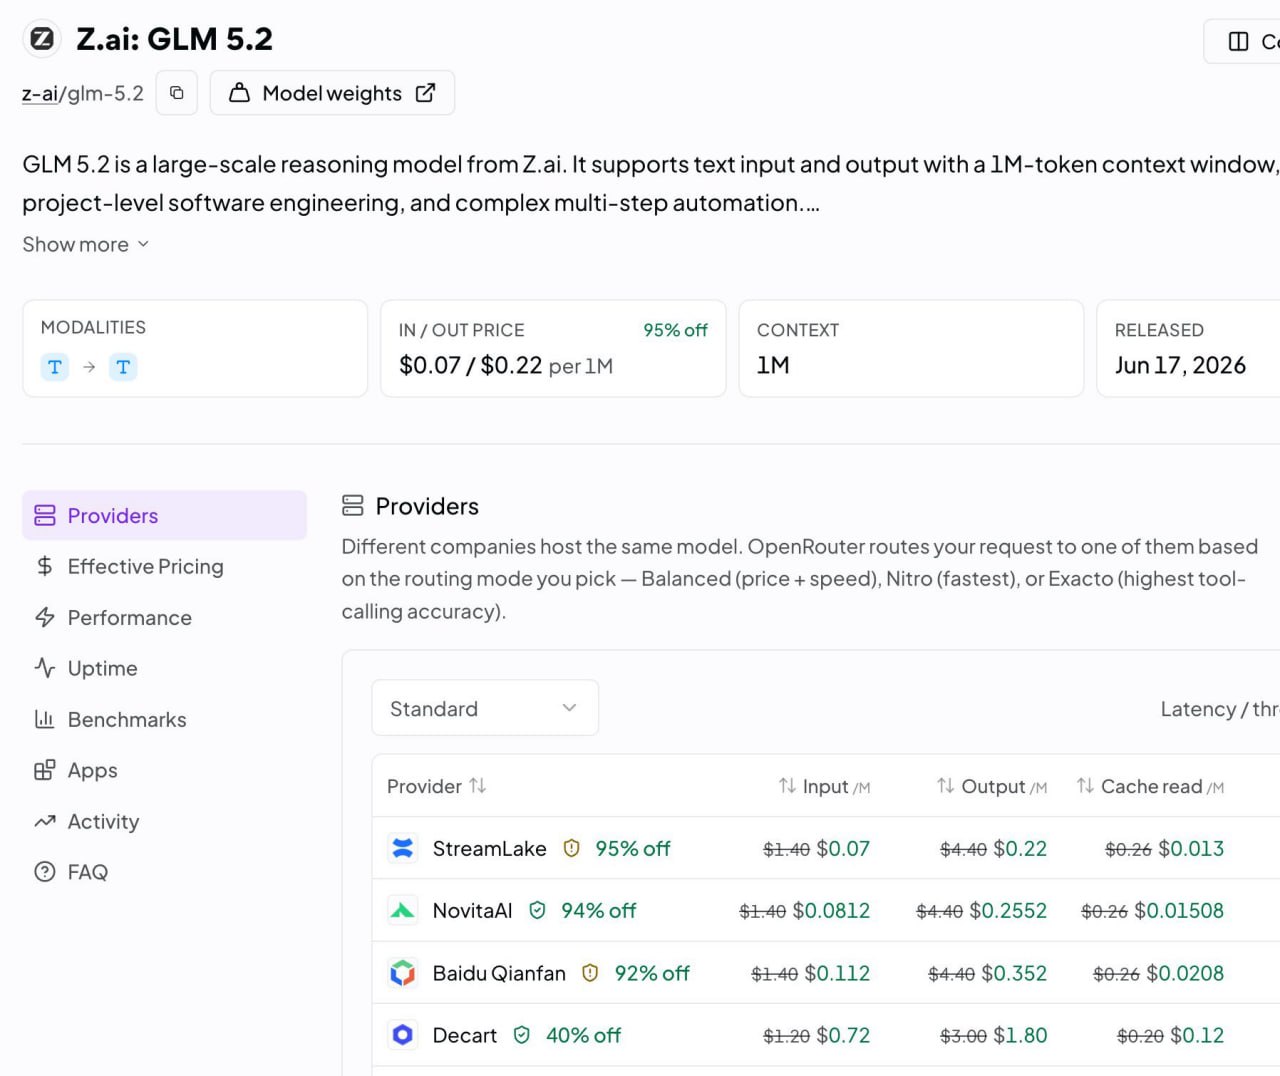
Zhipu's flagship GLM model price drops significantly to $0.07 per input token, making it cheaper than DeepSeek and practically free.
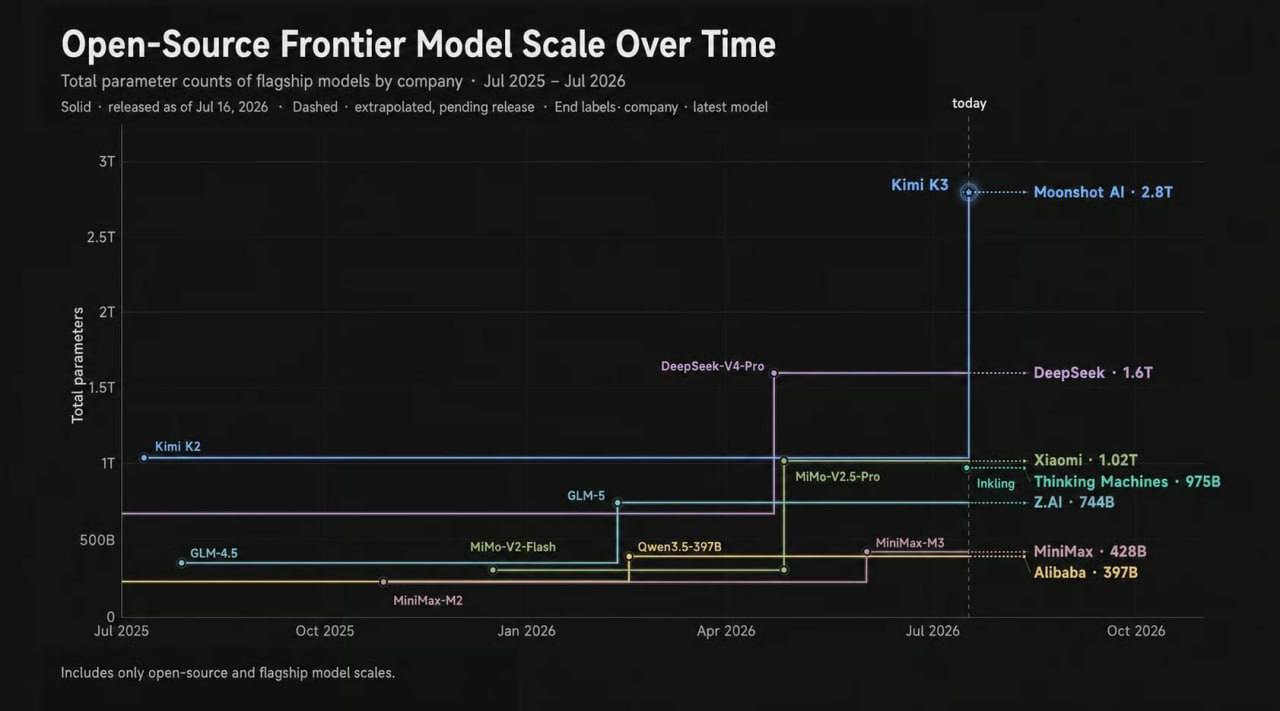
Moonshot unveils KIMI K3, a 2.8 trillion parameter MoE model with a 1M token context window, outperforming major models in knowledge-based tasks.